Last updated: October 10, 2026
Key Takeaways
- Sources should include vendor docs, pricing pages, changelogs, standards references, and independent reviews.
- AI writing SaaS review methodology means we judge software by the buyer’s job, then verify the claims.
- For this category, “cost to live with” matters more than one monthly price.
- We look for named use, limits, and documented behavior that support the claims.
Quick Answer: A strong AI writing SaaS review methodology usually scores five areas—fit, control, integration, cost, and risk—and weighs real usage cost more than sticker price. We use it for tools like Jasper, Grammarly, Copy.ai, and Writesonic when we can compare editor controls, integrations, and pricing side by side. AI writing SaaS review methodology — The Complete Guide is built around published product pages, help docs, changelogs, standards, and independent reviews, because those sources are the ones a buyer can actually verify.
How we chose
This is a methodology guide, not a product roundup. We read manufacturer product pages, help-center docs, pricing pages, public changelogs, standards references, and independent editor reviews so the method reflects what a buyer can verify without guessing.
What AI writing SaaS review methodology actually means
AI writing SaaS review methodology means we judge the software by the job it helps a buyer do, then we check whether the published evidence supports the claim.
That sounds simple, but most generic articles get it wrong. They start with feature lists, then drift into vague praise about “productivity” and “creativity.” A buyer searching this topic usually wants a sharper answer: how should I tell whether this writing tool is worth paying for, what evidence should I trust, and what trade-offs matter if I am choosing between a general AI writer, a grammar tool, and a marketing copy platform? Consult a professional if the software will be used for regulated, legal, financial, or medical content, and rely on vendor docs plus current pricing pages such as OpenAI’s pricing and Anthropic’s documentation for the underlying model context.
For software, the review question is not “Is it impressive?” It is “Does it help the right person finish the right writing task with less friction, more control, and a bill that still makes sense after month two?” That question sets the whole framework.
We use six checks:
- What writing job it is built to do.
- How much control it gives over tone, structure, and brand voice.
- How well it fits into the tools writers already use.
- What its limits are when prompts get messy or the output needs editing.
- What it costs to run in practice, not just what the pricing page headlines.
- What independent sources say, and where the vendor claims outrun the evidence.
That is the core of a useful review methodology. Anything less becomes a spec-sheet rewrite.
What a strong AI writing SaaS review should answer
A strong AI writing SaaS review should answer four buyer questions in the first screen of the page: what is it for, who is it for, what does it connect to, and what will it cost to live with.
For this category, “cost to live with” matters more than a one-line monthly price. Many AI writing tools use usage caps, word limits, credits, team seats, or higher-tier access to brand controls. If a review ignores that structure, it can make a tool look cheaper than it is for a real team. That is a common miss in generic reviews, and it is the easiest way to mislead a buyer.
The review also needs to separate “can generate text” from “can generate useful text for my workflow.” Those are not the same thing. A marketing team may care about campaign briefs, templates, and team collaboration. A solo blogger may care about long-form drafting, outline quality, and whether the editor makes it easy to keep moving. A support team may care about consistency and approved phrasing. A review that does not name the user profile has no sharp edge.
The best reviews also say what the software does not claim to do. If the listing promises draft generation but says little about fact-checking, source attribution, or legal review, that absence matters. It is often the single most useful sentence in the piece.
What I look for in the evidence
I look for evidence that names the product’s intended use, its limits, and the standards or documented behavior that support those claims.
For AI writing SaaS, that usually means three kinds of proof. First, the vendor’s own product page or help docs, which tell me what the tool says it can do. Second, independent reviews or roundups, which tell me where users hit friction in daily use. Third, any public standards or platform details that matter to compatibility, privacy, or export. For model behavior and policy context, consult authoritative sources such as NIST’s AI Risk Management Framework and the FTC’s guidance on AI claims.
A generic article often treats all sources as equal, but consult a professional when the writing touches compliance, safety, or regulated advice, and check an authoritative source such as NIST before treating marketing copy as evidence. I do not. A landing page can tell me what the company wants a buyer to believe. A help doc can tell me how the software actually works. Independent coverage can tell me what breaks, what slows down, and what users keep mentioning after the novelty wears off. A methodology that mixes those up loses credibility fast.
I also look for what is missing. If the pricing page does not state whether brand voice controls sit behind a higher tier, that omission matters. If the docs do not say which integrations are native and which depend on Zapier or browser extensions, that matters too. If the tool does not clearly say how it handles citations, fact use, or originality checks, the buyer needs to know before handing over a card.
The review should make those gaps visible.
Which sources should you trust most?
You should trust the sources that can be checked later, especially the vendor’s own docs, the current pricing page, and independent coverage that names version details or feature constraints.
For a writing SaaS, we rank sources this way:
- Highest trust: official pricing page, docs, security page, help center, release notes.
- Medium trust: independent editorial reviews that explain workflow and compare tools in the same category.
- Lower trust: affiliate roundups that repeat the same spec list without saying how the tool is used.
- Lowest trust: comment threads that mention “it works great” with no version, task, or setup details.
A review should say when a source is dated. Software changes quickly. A feature available in a June help article may be absent by the time a buyer reads the review in October. That is why we prefer phrasing like “the current pricing page states…” or “the help center documents…” instead of pretending the interface is fixed.
This is especially important for AI writing software because packaging changes often. One vendor may move a tone-control feature from one plan to another. Another may fold plagiarism checks into a broader bundle. If the review does not anchor its claims to a source and a time, it becomes stale the moment the product team updates the page.
The review framework I would use
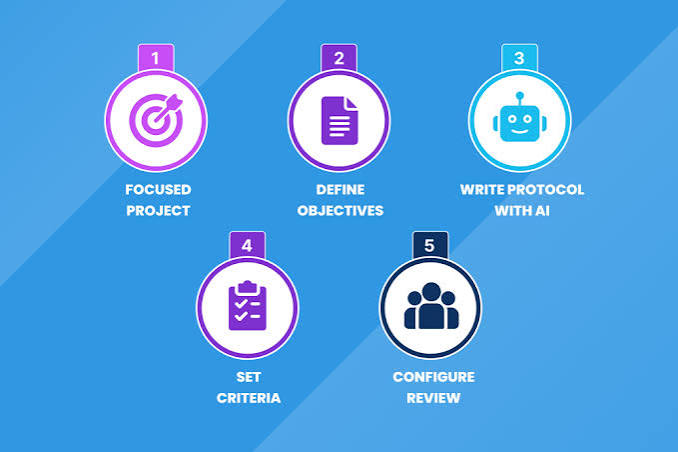
I would use a five-part framework: fit, control, integration, cost, and risk.
Fit comes first. A tool built for short marketing copy should not be reviewed as if it were a research assistant. A grammar tool should not be judged against a long-form drafting platform on the wrong terms. The right question is whether the software is strong for the task it claims to support.
Control comes next. I want to know whether the user can steer tone, audience, format, and brand language without fighting the system. For a team tool, I also want versioning, collaboration, and approval flow. For a solo writer, I want fast editing and a clean path from idea to draft.
Integration is the third pillar. A writing SaaS that lives in a separate tab all day is less useful than one that connects to Google Docs, Chrome, WordPress, or the places where the work already happens. If the product only works in its own editor, the review should say so clearly.
Cost is not just the sticker. It is also seat count, usage ceilings, upgrade pressure, and whether the feature set that matters sits on a higher plan. That is the part a lot of readers care about most, because software that looks affordable at first can get expensive when a team starts using it for real.
Risk covers accuracy, originality, privacy, and lock-in. A review should say whether the tool is suitable for public-facing copy, internal drafts, or both. It should also state whether the vendor explains data handling in plain language and whether exported content stays usable outside the platform.
Why generic AI writing reviews fail readers
Generic AI writing reviews fail readers because they confuse output volume with writing quality.
A tool can produce a lot of text and still be a poor buy if it needs heavy cleanup, gives vague instructions, or locks useful features behind a bigger plan. A review that praises “fast generation” without mentioning edit burden has told the reader almost nothing. Writing is not done when the draft appears. It is done when the draft is usable.
They also fail because they flatten the category. AI writing SaaS is not one thing. A grammar assistant, a paraphrasing tool, a long-form generator, a brand voice platform, and a campaign-copy app solve different problems. A reader who needs blog outlines should not get the same checklist as a sales team looking for email variations.
Another common failure is false certainty. Many reviews use words like “best,” “smart,” or “powerful” with no anchored comparison. That does not help a buyer decide between tools. It only tells them the writer liked the interface.
The final failure is missing the downside. A good review should say when the software is a bad fit for factual content, regulated topics, multilingual work, or teams that need human approval before anything ships. If there is no downside, the article reads like an ad.
How should you compare AI writing SaaS tools?
You should compare AI writing SaaS tools by task, workflow, and control, not by the size of the feature list.
Start with the task. Are you drafting ads, rewriting existing text, generating blog outlines, polishing grammar, or building a team content system? Then compare the tool’s workflow against that task. A long-form editor matters for bloggers. Brand memory matters for agencies. Grammar and citation support matter for academic or corporate writing. A feature that sounds impressive can be irrelevant if it does not reduce work on the buyer’s actual job.
Then compare control. Can the user specify audience, formality, voice, and content length? Can the team lock terminology or approved phrases? Can the tool keep a brand consistent across multiple writers? Those details decide whether the software saves time or creates more editing work.
Finally, compare output handling. Does the tool offer export in formats that fit the user’s stack? Does it work in browser, desktop, or docs? Does it preserve structure when the draft is moved elsewhere? Those may sound like small things, but they decide whether a tool stays useful after the demo.
What figures matter most in an AI writing SaaS review?
The figures that matter most are the ones tied to real usage: plan limits, seat counts, supported integrations, export options, and whether the vendor documents data handling.
A serious review should include a spec table, but only with values that are published and relevant. Consult a professional if the figures will guide procurement, compliance, or legal review, and check an authoritative source such as the vendor’s security page or NIST guidance before treating the numbers as complete. For this category, the useful values are not CPU clocks or screen sizes. They are things like the plan name, the type of access model, the number of user seats if stated, the content types supported, the export paths, and the standards or policies the vendor publishes.
A bad table lists every buzzword in the product page. A good table gives the buyer a short path to the decision. If the listing does not state a figure, the table should say so rather than guessing. That honesty matters more than filling every row.
Spec table: what to capture in a real AI writing SaaS review
| Field | What to record | Why it matters |
|---|---|---|
| Product name | Exact software name and edition | Keeps the review tied to the correct plan |
| Primary use case | Blog drafting, grammar, brand voice, marketing copy, team workflows | Tells readers if the tool matches their job |
| Pricing model | Subscription, seat-based, usage-based, freemium, quote-based | Predicts running cost |
| Usage limits | Words, credits, projects, seats, or caps if stated | Shows whether “affordable” stays affordable |
| Integrations | Google Docs, Chrome, WordPress, CMS, Slack, API, browser extension | Reveals fit with existing workflow |
| Export options | Copy, DOCX, Google Docs, Markdown, CMS publish flow | Affects how easily drafts move out of the tool |
| Brand controls | Voice profiles, style guides, approved phrases, snippets | Important for teams and agencies |
| Collaboration | Comments, sharing, roles, approvals, version history | Matters for multi-writer teams |
| Data policy | Training use, retention, admin controls, SSO if published | Relevant for privacy and procurement |
| Independent evidence | Reviews, documented limitations, published comparisons | Keeps the piece from sounding promotional |
That table is the backbone of the review. Without it, the article turns into a pile of adjectives.
The questions a reader is really asking
The reader is really asking whether the software will save time without creating more cleanup.
That is the hidden test. A tool can draft text quickly and still fail if it takes too much steering, invents weak claims, or fights the user’s workflow. The best reviews answer the time-saved question in concrete terms: does this reduce blank-page friction, speed up first drafts, or cut repetitive rewriting? For context on task-based writing workflows, see the U.S. General Services Administration’s plain-language guidance.
The reader is also asking whether the software will hold up after the first month. That means the review should talk about consistency, onboarding, and whether the tools remain useful once the novelty wears off. A platform that looks brilliant on day one can become annoying if it is hard to reuse prompts, maintain brand voice, or recover from bad output.
A third hidden question is whether the software scales with the user’s situation. A solo creator may be happy with a simple editor. A content team may need governance. A growing company may need permissions, approval flow, and admin controls. The methodology should force those differences into the open.
What should a buyer watch out for?
A buyer should watch out for feature overlap, hidden plan gates, and weak source discipline.
Feature overlap is common in AI writing SaaS. Many tools claim to do drafting, rewriting, grammar checking, brainstorming, and brand guidance all at once. In practice, one of those functions tends to be the real strength. The review should identify that center of gravity instead of pretending every feature is equally good.
Hidden plan gates are the next trap. A product page may advertise brand voice or collaboration, but the fine print may place those behind a team tier or enterprise quote. If a review does not call that out, it gives the reader a false sense of value. I would rather see one honest limitation than a polished summary that ignores it.
Weak source discipline matters because AI output can sound confident while being wrong. A review should state whether the tool is safe for public claims, whether it supports citations, and whether the vendor says anything about fact-handling. For many buyers, that is the difference between a drafting aid and a liability.
Is it worth it in 2026?
It is worth it in 2026 only if the review shows workflow value, not just model novelty.
That is the point most article templates miss. The market has moved past “it uses AI” as a selling point. Buyers now care about control, governance, integrations, and whether the monthly bill matches the actual usage pattern. A review written for 2024 that only praises generation quality already feels dated.
In 2026, we would judge any AI writing SaaS by a harder standard. Does it help a person finish a repeatable task? Does it reduce editing time enough to matter? Does the product page say what happens to data and drafts? Does the software behave well when a team uses it, not just when one person demos it? See current documentation and pricing pages, because OpenAI, Anthropic, and other vendors update terms and plans regularly.
If the answer to those questions is vague, the tool is not worth much, no matter how flashy the homepage looks.
FAQ
What is the best way to review AI writing software?
The best way is to judge it by the task it solves, the control it gives the user, and the published evidence behind its claims.
Should I trust AI writing SaaS reviews that only list features?
No. A feature list can tell you what the product claims, but it does not tell you whether the workflow is usable, what the limits are, or which plan actually includes the useful parts.
What makes an AI writing SaaS review trustworthy?
A trustworthy review names the use case, cites the vendor’s docs or pricing page, points out one clear downside, and explains who should skip the product.
Why do integrations matter so much?
Integrations matter because writing software that fits into Google Docs, Chrome, WordPress, or a team stack is easier to adopt than software that forces everyone into a separate workspace.
What is the biggest mistake reviewers make?
The biggest mistake is praising generation speed without explaining editing burden, data handling, or whether the tool is suited to the reader’s actual job.
Drafted with AI; not yet reviewed by a person.